Problem
The Brand Department needed to identify key factors affecting Customer Satisfaction and detect sudden sentiment changes using NLP analysis on Twitter, in order to proactively prevent customer churn.
Resolve and Result
- Data Collection:
- Data collected with python library using list relevant keyword.
- Data Cleaning:
- Remove Official Acc, Duplicate Tweet, Promotion Tweet
- Remove Spam or Undetected Duplicate
- Remove Buzzer Tweet
- Remove Unnecessary characters (Number, Emoji, Mention, etc.)
- Stopword Removal
- Stemming word
- Slang Words changer
- EDA (Exploratory Data Analysis):
- Categorization based on keyword
- Sudden changes by Customer (Positive to negative or otherwise)
- Getting additional tweet location by text
- Hashtag analysis
- Data Modeling:
- Labelling Data using Fleiss’ Kappa rules
- Train, Test, Validation split (0.7, 0.2, 0.1)
- Tokenization and building vocabulary
- Model creation using Bidirectional LSTM (Pytorch)
- Data Training and Hyperparameter Optimization (Gridsearch)
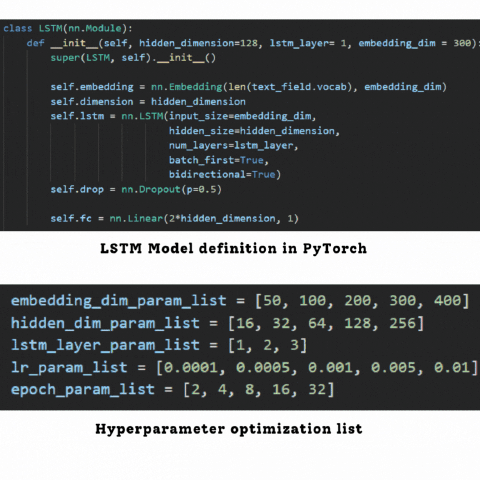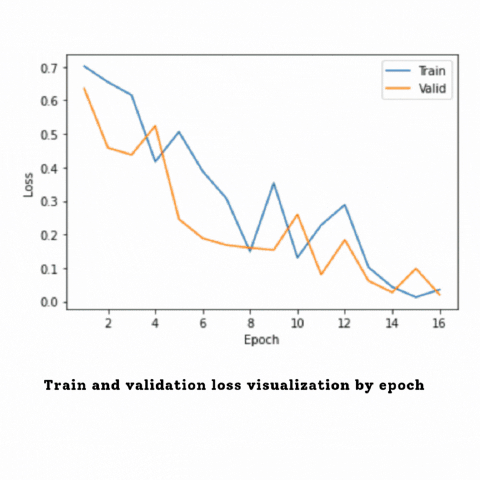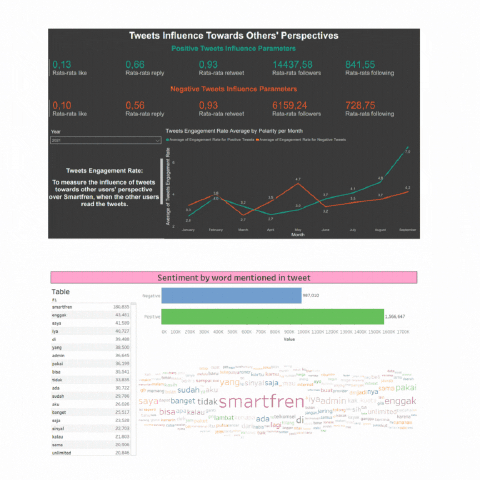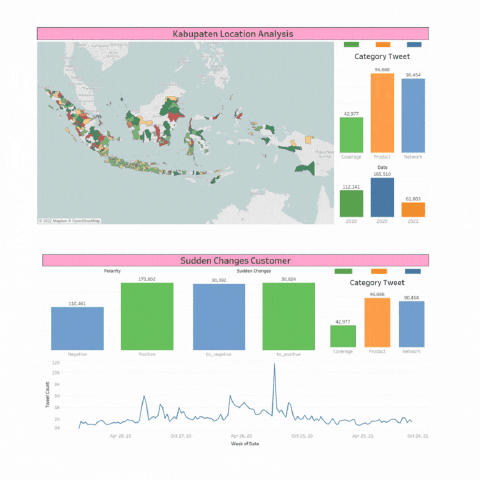
- Evaluation and Visualization
🏆 Results
The model got an f1-score with 92% accuracy, Train loss is 0.035, and validation loss is 0.020. It means the model I create has a great result to be deployed.